Kubernetes is a container orchestration platform, it allows you to run many containerised workloads (applications) in a scalable, secure, reliable and adaptable way. It is however quite complex to build and manage. To explore a Kubernetes deployment we are going to be using Kubespray to deploy and manage a Kubernetes cluster which is built upon Ubuntu Linux 24.04 LTS; you can build it with Kubernetes the Hard Way, but instead we are going to deploy with Kubespray.
Kubespray is in essence an Ansible Playbook, which contains everything you need to complete a deployment, it includes various configurations (some of which we’ll be exploring through this series) to customise/configure your deployment to your needs. It is worth noting that Kubespray deploys a production grade deployment, with a High Availability control plane. However, if you were to use it in production you’d want to ensure you are also adding sufficient logging, security, monitoring, automation and backup/restoration aspects to meet your requirements.
Imperative vs Declaritive
Within Kubernetes (and more generally in computing) there is a the concept of Imperative commands and Declarative commands (statements).
An Imperative is a command, like “create 10 pods of X”.
Whilst Declartive is a statement, for example: “I want 10 pods of X to exist”.
In terms of Kubernetes and within this series, we will tend to use Declartive statements in the form of YAML files, which will state how we want the Kubernetes cluster (and its workloads to look). We may also use Imperative commands, but will tend away from these because within a Infrastructure as Code type workflow, you’d not want people punching commands into clusters, because they may not persist if also combined with Delcaritive management techniques.
Basic Server Deployment
I have deployed six Ubuntu Linux 24.04 LTS virtual machines, all on the same network subnet, each has a 200GB root disk, 32GB of RAM and 4 vCPU.
They will be configured as follows:
- tris-k8lab-01 – Management Workstation (not part of Kubernetes cluster)
- tris-k8lab-02 – Kubernetes Cluster – Control Plane Node 1
- tris-k8lab-03 – Kubernetes Cluster – Control Plane Node 2
- tris-k8lab-04 – Kubernetes Cluster – Control Plane Node 3
- tris-k8lab-05 – Kubernetes Cluster – Worker Node 1
- tris-k8lab-06 – Kubernetes Cluster – Worker Node 2
Kubernetes is split into a Control Plane and (Worker) Nodes, we are going to have three Control Plane nodes which will run the Kubernetes control plane components used to run the Kubernetes cluster and for now two Worker Nodes which will be used to run the containers.
Kubernetes Component Introduction
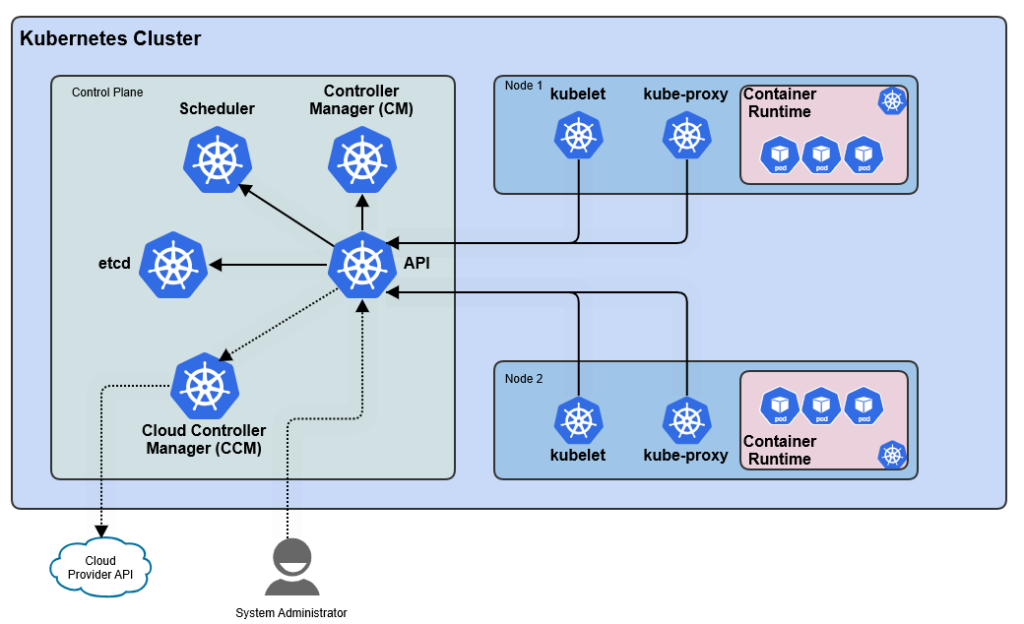
A picture paints a thousand words, so here is a simple diagram of a Kubernetes cluster with all the various essential components that make it up. We’ll then briefly describe what each is then for.
Control Plane Components
These are the control plane components, the components of the Kubernetes platform that manage the workloads (containers/pods) that are deployed onto the cluster.
API Server (kube-apiserver)
The API Server is the RESTful API that is presented over HTTP(S) for use by both System Administrators and the various components of the Kubernetes cluster.
etcd
The etcd is a key value store, which stores all of the API server data, its the configuration of the cluster, what is where and is highly available, because without it, you have no cluster!
Scheduler (kube-scheduler)
The scheduler is the component that assigns containers (pods) to suitable (Worker) Nodes, i.e. scheduling them for operation.
Controller Manager (kube-controller-manager)
Kubernetes works akin to a finite state machine in that the cluster is in one particular state, then there are changes required to another state. The Controller Manager is what ensures the change of state happens, by watching the API it determines if there is a difference between the current state and the desired state, and if there is, it does the do to move the cluster to that new state.
Cloud Controller Manager (cloud-controller-manager)
An optional component, but allows for the cloud specific logic that allows the Kubernetes cluster to interact with the cloud platform components directly. It can ensure that the underlying cloud resources are available to service the Kubernetes cluster as the Controller Manager requires via the Kubernetes API; which in turn drives the cloud provider’s API (via the Cloud Controller Manager).
(Worker) Node Components
These components run on every (worker) node to run and manage the pods to actually provide the space for running containerised workloads (applications).
kubelet
The kubelet is a component on each (worker) node that ensures that Pods are running and includes that their container(s) within are also running, and in the expected state.
Remember that a pod is not a container, a pod is the smallest unit of compute within the Kubernetes cluster, typically a pod will run one container, but it also might also run more than one, perhaps what is known as a “sidecar” to provide some additional functionality (e.g. networking).
Container Runtime
A key part of Kubernetes is the container runtime, this is the component that actually runs the container(s) on the (worker) node. Kubernetes supports a number of different container runtimes, so you’re not stuck with just Docker. Using the Container Runtime Interface (CRI), you can use any container runtime that can integrate with CRI, some exampels are Docker, CRI-O and containerd, we’re going to use containerd within this series because its simple, lightweight and does just what we need, no frills.
kube-proxy
The kube-proxy is a network proxy that runs on all the (worker) nodes of your cluster. It allows network communication to and from the pods in your cluster to other pods within your cluster, but also to network resources (or clients) outside of your Kubernetes cluster. It is actually optional, and instead you can use a different Network Plugin which is another software component which uses the Container Network Interface (CNI) specification to allow pods to communicate within and outside of the Kubernetes cluster as required. A CNI (Container Network Interface) plugin is responsible for providing networking between Pods and, depending on the plugin, may also provide network policy enforcement, routing, encryption, and load balancing.
Some examples of these CNI plugs are Calico (which we’ll be using in this series), Cilium, Flannel, the list goes on, each has its advantages, disadvantages and feature sets.
Management Workstation Preparation
Now you have an idea of the components, let’s start our deployment. Within this series there will be some things that i’ll assume you as reasonbly confident Linux user will know how to do, so I won’t go into detail, but other things I may dig deeper into the steps required so you can see how these steps are used to support an overall deployment.
Install Ansible
Install Ansible with the following:
sudo apt install ansibleInstall and Configure Git
Install Git with:
sudo apt install gitYou’ll need to have installed Git on your Management Workstation, then before you go any further configure Git ready for use.
git config --global user.name "johndoe"
git config --global user.email "your_email@example.com"
We’ll need an SSH Keypair both for adminsitering our cluster but also so we can use for Git authentication, so we’ll generate an SSH Keypair now with the following:
ssh-keygen -t ed25519 -C "your_email@example.com"
eval "$(ssh-agent -s)"
ssh-add ~/.ssh/id_ed25519
Upload SSH Public Key to Git
Go to GitHub → Settings → SSH and GPG keys → New SSH key, paste the key (you can see with the below), and save it.
cat ~/.ssh/id_ed25519.pubTest it works with;
ssh -T git@github.comNow your workstation is prepared, we can then go onto actually configuring and deploying Kubespray.
Clone Kubespray and Configure Virtual Environment
Clone the Kubespray repository to your machine with:
git clone https://github.com/kubernetes-sigs/kubespray.gitThen setup the virtual environment, we’ll install the Virtual Environment into the same directory as the cloned Kubespray repository.
cd kubespray

apt install python3.12-venv

python3 -m venv .venv
source .venv/bin/activate
pip install -U -r requirements.txt
Setup SSH Keys for all Nodes
I’m going to use the key I generated earlier across all of the nodes, so I should then be able to SSH without password to all of the other nodes in the cluster from this first node.
ssh-copy-id -i ~/.ssh/id_ed25519.pub tris@tris-k8slab-02
ssh-copy-id -i ~/.ssh/id_ed25519.pub tris@tris-k8slab-03
ssh-copy-id -i ~/.ssh/id_ed25519.pub tris@tris-k8slab-04
ssh-copy-id -i ~/.ssh/id_ed25519.pub tris@tris-k8slab-05
ssh-copy-id -i ~/.ssh/id_ed25519.pub tris@tris-k8slab-06
Obviously you need to enter your password this time round, but once copied test you can connect to each node without needing a password, for example:
ssh -i ~/.ssh/id_ed25519 tris@tris-k8slab-02Configure for Sudo
We’ll need each server to allow this user to get sudo without a password, so on each server ensure the following:
sudo visudoAdd the user to the file (same as root):
tristan ALL=(ALL:ALL) ALL NOPASSWD: ALLYou should now be able to SSH to a server as this user and gain sudo without re-entering the user’s password.
Create Inventory
Kubespray comes with a sample inventory.
We’re going to call the cluster: k8scluster1, so we’ll copy everything from the sample to a new directory, which we’ll then use for our deployment.
cd ~/kubespray
cp -rfp inventory/sample inventory/k8scluster1
Create Our Inventory
We can now create our inventory, we’re going to start with the following set of servers.
The first server will be our management workstation:
- tris-k8slab-01 – Management Workstation
Then the actual Kubernetes cluster will be the following set of servers:
- tris-k8slab-02 – Control Plane
- tris-k8slab-03 – Control Plane
- tris-k8slab-04 – Control Plane
- tris-k8slab-05 – Node (Worker)
- tris-k8slab-06 – Node (Worker)
Within the ~/kubespray/inventory/k8scluster1 directory, you’ll find a file called inventory.ini, its this we’ll add our configuration to; which is explained below:
# This inventory describe a HA typology with stacked etcd (== same nodes as control plane)
# and 3 worker nodes
# See https://docs.ansible.com/ansible/latest/inventory_guide/intro_inventory.html
# for tips on building your # inventory

# Configure 'ip' variable to bind kubernetes services on a different ip than the default iface
# We should set etcd_member_name for etcd cluster. The node that are not etcd members do not need to set the value,
# or can set the empty string value.
[all]
tris-k8slab-02 ansible_host=192.168.101.152 etcd_member_name=tris-k8slab-02 ansible_user=tris
tris-k8slab-03 ansible_host=192.168.101.153 etcd_member_name=tris-k8slab-03 ansible_user=tris
tris-k8slab-04 ansible_host=192.168.101.154 etcd_member_name=tris-k8slab-04 ansible_user=tris
tris-k8slab-05 ansible_host=192.168.101.155 ansible_user=tris
tris-k8slab-06 ansible_host=192.168.101.156 ansible_user=tris

[kube_control_plane]
tris-k8slab-02
tris-k8slab-03
tris-k8slab-04

[etcd]
tris-k8slab-02
tris-k8slab-03
tris-k8slab-04

[kube_node]
tris-k8slab-05
tris-k8slab-06

[calico_rr]

[etcd:children]
kube_control_plane
kube_node
calico_rr
We’re having a fairly straightforward setup to start with. All our nodes are on the same layer 2 VLAN.
We add all our nodes to the “[all]” group.
Then we’re going to have nodes 02, 03 and 04 as Kubernetes Control Plane Nodes, so those are added to the “[kube_control_plane]” group, the these same set of nodes with run the etcd key value store, so we include those in the “[etcd]” group.
We want to have two (worker) nodes so those two 05 and 06 are added to the “[kube_node]” group.
You’ll notice the “[calico_rr]” group, we’re not using this, the group states which nodes would be Calico Route Reflectors. Although an advanced topic, it helps avoid the problems with iBGP which is used by Calico to track network pathways to pods. Each Kubernetes node becomes node within BGP, a full mesh is required, meaning that on large clusters with many nodes this can get very difficult and complex to manage because each node must have peerings to every other node. For a 3 node cluster that’s only 3 peerings. For a 10 node cluster that’s 45 peerings (sessions) and then it just gets worse from there!
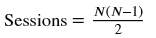
Once the inventory has been configured to include all our nodes, we can progress onto configuring specific settings for our cluster.
Configure Kubespray Variables
We firstly need to edit the ~/kubespray/inventory/k8scluster1/group_vars/all/all.yaml file to specify some settings.
DNS Servers
We need to set what we want to the DNS servers to be, typically you’ll want these to be your Internal DNS servers:
~/kubespray/inventory/k8scluster1/group_vars/all/all.yaml
...
# Upstream dns servers
upstream_dns_servers:
  - 192.168.101.10
...
Set the Cluster Name, which appears in ~/kubespray/inventory/k8scluster1/group_vars/k8s_cluster/k8s_cluster.yml as a FQDN option.
Container Runtimes (CRI)
Next we are going to specify the container runtime which we want to use on our Kubernetes cluster, we discussed what possible types there are for these container runtimes earlier, we’re going to use “containerd”.
~/kubespray/inventory/k8scluster1/group_vars/k8s_cluster/k8s_cluster.yml
...
## Container runtime
## docker for docker, crio for cri-o and containerd for containerd.
## Default: containerd
container_manager: containerd
...
Other Configurations
We have the CoreOS settings and the etcd Settings, these files we’re not going to be changing.
- coreos.yaml
- etcd.yaml (Additional Information)
Container Networking Interface (CNI)
We’re going to be using Calico for the CNI, we briefly discussed this earlier in a previous section.
~/kubespray/inventory/k8scluster1/group_vars/k8s_cluster/k8s_cluster.yml
...
# Choose network plugin (cilium, calico, kube-ovn, weave or flannel. Use cni for generic cni plugin)
# Can also be set to 'cloud', which lets the cloud provider setup appropriate routing
kube_network_plugin: calico
...
We can also set the internal CIDRs used within our Kubernetes cluster, it is recommended that these don’t overlap with your other internal CIDR ranges, this can become problmatic, so remember to ensure you IPAM allocations are sound.
~/kubespray/inventory/k8scluster1/group_vars/k8s_cluster/k8s_cluster.yml
...
# Kubernetes internal network for services, unused block of space.
kube_service_addresses: 10.233.0.0/18

# internal network. When used, it will assign IP
# addresses from this range to individual pods.
# This network must be unused in your network infrastructure!
kube_pods_subnet: 10.233.64.0/18
...
Optional IPv6 Dual Stack Configuration
To enable IPv6, you can update your inventory to include the IPv6 address on the end if you so wish:
~/kubespray/inventory/k8scluster1/inventory.ini
[all]
tris-k8slab-02 ansible_host=192.168.101.152 etcd_member_name=tris-k8slab-02 ansible_user=tris ip=192.168.101.152 ip6="2001:1234:5678::2"
tris-k8slab-03 ansible_host=192.168.101.153 etcd_member_name=tris-k8slab-03 ansible_user=tris ip=192.168.101.153 ip6="2001:1234:5678::3"
tris-k8slab-04 ansible_host=192.168.101.154 etcd_member_name=tris-k8slab-04 ansible_user=tris ip=192.168.101.154 ip6="2001:1234:5678::4"
tris-k8slab-05 ansible_host=192.168.101.155 ansible_user=tris ip=192.168.101.155 ip6="2001:1234:5678::5"
tris-k8slab-06 ansible_host=192.168.101.156 ansible_user=tris ip=192.168.101.156 ip6="2001:1234:5678::6"
If you then also edit this file and enable the IPv6 dual stack function.
~/kubespray/inventory/k8scluster1/group_vars/k8s_cluster/k8s_cluster.yml
...
enable_dual_stack_networks: true
...
Addons
Kubespray provides the ability to use Addons as well. These additional YAML files allow you to add useful additional features to your cluster.
The one we are going to enable first is kube-vip, this is a Virtual IP (VIP) Solution that provides load balancing (and high availability) for the Kubernetes API server; you can use it as either ARP or BGP modes.
Enable Kube-VIP
To do this firstly change this setting in the k8s-cluster.yaml file:
~/kubespray/inventory/k8scluster1/group_vars/k8s_cluster/k8s_cluster.yml
kube_proxy_strict_arp: trueNow we need to enable the configuration within the addons.yaml file too:
~/kubespray/inventory/k8scluster1/group_vars/k8s_cluster/addons.yml
kube_vip_enabled: true
kube_vip_arp_enabled: true
kube_vip_controlplane_enabled: true
kube_vip_address: <YOUR VIP ADDRESS> e.g. 192.168.101.157
loadbalancer_apiserver:
  address: "{{ kube_vip_address }}"
  port: 6443
kube_vip_lb_enable: true
kube_vip_interface: eno1
kube_vip_services_enabled: true
kube_vip_dns_mode: first
kube_vip_cp_detect: false
kube_vip_leasename: plndr-cp-lock
kube_vip_enable_node_labeling: true
Replace with an unused static IP in your subnet that all control plane nodes can access. Here’s what the key options do (for a full list see the docs or source ):
My file was missing: kube_vip_lb_enable, so I needed to add that and set it to “true”.
Deploy
We are now ready to deploy, run from the ~/kubespray directory:
ansible-playbook -i inventory/k8scluster1/inventory.ini cluster.yml -K -b -v --private-key=~/.ssh/id_ed25519Add -K for the become user password, leave blank.
Kubectl Management Tool
To manage Kubernetes we need to install kubectl on our Management Workstation. To do that we use:
sudo apt-get install -y apt-transport-https ca-certificates curl gnupg

curl -fsSL https://pkgs.k8s.io/core:/stable:/v1.34/deb/Release.key | \
sudo gpg --dearmor -o /etc/apt/keyrings/kubernetes-apt-keyring.gpg

echo 'deb [signed-by=/etc/apt/keyrings/kubernetes-apt-keyring.gpg] https://pkgs.k8s.io/core:/stable:/v1.34/deb/ /' | \
sudo tee /etc/apt/sources.list.d/kubernetes.list

sudo apt-get update
sudo apt-get install -y kubectl

kubectl version --client
Getting admin.conf for the Cluster
Now that Kubectl is installed, we need to configure its credentials.
We’re going to basically be connecting as the Kubernetes Cluster Admin, but we’ll setup some other accounts later on.
The easiest way to get hold of the credentials is to get them from a node by copying admin.config from/etc/kubernetes to within your home directory on one of the Control Nodes.
And then, so on the Management Workstation do the following to copy from that location to your local workstation machine:
mkdir -p ~/.kube
touch ~/.kube/config
chmod 700 ~/.kube
chmod 600 ~/.kube/config

scp -i ~/.ssh/id_ed25519 tris@tris-k8slab-02:/home/tris/admin.conf ~/.kube/config
If you have rebuilt your cluster, you may find there are problems connecting, for example:
kubectl get nodes
E0721 18:10:42.609399  384662 memcache.go:265] "Unhandled Error" err="couldn't get current server API group list: Get \"https://192.168.101.157:6443/api?timeout=32s\": tls: failed to verify certificate: x509: certificate signed by unknown authority (possibly because of \"crypto/rsa: verification error\" while trying to verify candidate authority certificate \"kubernetes\")"
E0721 18:10:42.615675  384662 memcache.go:265] "Unhandled Error" err="couldn't get current server API group list: Get \"https://192.168.101.157:6443/api?timeout=32s\": tls: failed to verify certificate: x509: certificate signed by unknown authority (possibly because of \"crypto/rsa: verification error\" while trying to verify candidate authority certificate \"kubernetes\")"
To resolve this, you just need to ensure your Kubeconfig file is updated with the new Kubernetes CA certificate:
cp ~/.kube/config ~/.kube/config.old
ssh -i ~/.ssh/id_ed25519 tris@tris-k8slab-02 'sudo cat /etc/kubernetes/admin.conf' > ~/.kube/config
chmod 600 ~/.kube/config
Then try again:
kubectl get nodesAnd you should find it works.
You may need to update the Kubctl config file to specify the VIP of the Kubernetes API instead perhaps of just one node, look for this section within the file and change the IP accordingly:
apiVersion: v1
clusters:
- cluster:
    certificate-authority-data: "<BIG LONG STRING>
    server: https://192.168.10.157:6443 # <-- You may need to change this value to your VIP.
  name: cluster.local
contexts:
# ...
Test Connection
As we have kubectl installed, let’s try and get some information.
$ kubectl get nodes
NAME             STATUS   ROLES           AGE   VERSION
tris-k8slab-02   Ready    control-plane   18h   v1.36.2
tris-k8slab-03   Ready    control-plane   18h   v1.36.2
tris-k8slab-04   Ready    control-plane   18h   v1.36.2
tris-k8slab-05   Ready              18h   v1.36.2
tris-k8slab-06   Ready              18h   v1.36.2
If we get this, we can see that we have a working cluster and also that we can connect using Kubectl to administer it (as admin).
We’ll go into how contexts work for multiple users in a later article in the series.
Fix node label
kubectl label nodes tris-k8slab-05 kubernetes.io/role=worker
kubectl label nodes tris-k8slab-06 kubernetes.io/role=worker
Check Control Plane Pods
If we have a quick look at the pods within the “kube-system” namepace we can see we have lots of duplication, which is what we want for the control plane to be Highly Available.
$ kubectl get pods,svc --all-namespaces
NAMESPACE     NAME                                           READY   STATUS    RESTARTS   AGE
kube-system   pod/calico-kube-controllers-5f56575fc9-s2mgn   1/1     Running   0          18h
kube-system   pod/calico-node-56k4c                          1/1     Running   0          18h
kube-system   pod/calico-node-ghwnc                          1/1     Running   0          18h
kube-system   pod/calico-node-hlxkg                          1/1     Running   0          18h
kube-system   pod/calico-node-s44nt                          1/1     Running   0          18h
kube-system   pod/calico-node-wz2cg                          1/1     Running   0          18h
kube-system   pod/coredns-686f9bfd89-hc9vn                   1/1     Running   0          18h
kube-system   pod/coredns-686f9bfd89-lcxzc                   1/1     Running   0          18h
kube-system   pod/dns-autoscaler-656d6c8f96-pl9bx            1/1     Running   0          18h
kube-system   pod/kube-apiserver-tris-k8slab-02              1/1     Running   0          18h
kube-system   pod/kube-apiserver-tris-k8slab-03              1/1     Running   0          18h
kube-system   pod/kube-apiserver-tris-k8slab-04              1/1     Running   0          18h
kube-system   pod/kube-controller-manager-tris-k8slab-02     1/1     Running   0          18h
kube-system   pod/kube-controller-manager-tris-k8slab-03     1/1     Running   0          18h
kube-system   pod/kube-controller-manager-tris-k8slab-04     1/1     Running   0          18h
kube-system   pod/kube-proxy-bbwkl                           1/1     Running   0          18h
kube-system   pod/kube-proxy-btt2z                           1/1     Running   0          18h
kube-system   pod/kube-proxy-c9dxx                           1/1     Running   0          18h
kube-system   pod/kube-proxy-dshw7                           1/1     Running   0          18h
kube-system   pod/kube-proxy-fsbx4                           1/1     Running   0          18h
kube-system   pod/kube-scheduler-tris-k8slab-02              1/1     Running   0          18h
kube-system   pod/kube-scheduler-tris-k8slab-03              1/1     Running   0          18h
kube-system   pod/kube-scheduler-tris-k8slab-04              1/1     Running   0          18h
kube-system   pod/kube-vip-tris-k8slab-02                    1/1     Running   0          18h
kube-system   pod/kube-vip-tris-k8slab-03                    1/1     Running   0          18h
kube-system   pod/kube-vip-tris-k8slab-04                    1/1     Running   0          18h
kube-system   pod/nodelocaldns-24khm                         1/1     Running   0          18h
kube-system   pod/nodelocaldns-5psgt                         1/1     Running   0          18h
kube-system   pod/nodelocaldns-7fvvq                         1/1     Running   0          18h
kube-system   pod/nodelocaldns-9qn7w                         1/1     Running   0          18h
kube-system   pod/nodelocaldns-hrbrt                         1/1     Running   0          18h

NAMESPACE     NAME                 TYPE        CLUSTER-IP   EXTERNAL-IP   PORT(S)                  AGE
default       service/kubernetes   ClusterIP   10.233.0.1           443/TCP                  18h
kube-system   service/coredns      ClusterIP   10.233.0.3           53/UDP,53/TCP,9153/TCP   18h


$ kubectl config current-context
kubernetes-admin@cluster.local
Adding a Third and Fourth Worker Node
We build a new servers for these additional worker nodes we now want to add, after the initial installation.
We ensure that the new servers are also on the same network as the other nodes (and management workstation) and is running: Ubuntu 24.04 LTS Linux same as the others.
Copy SSH Key and Sudoers Configuration
We then need to copy the SSH key from the Management Workstation (tris-k8slab-01) to the new server: tris-k8slab-07 in this case, then ensure we can reach it and logon via the network. If it looks like its all there, we can progress to add it to the Ansible and deploy it as an additional worker node.
ssh-copy-id -i ~/.ssh/id_ed25519.pub tris@tris-k8slab-07
ssh-copy-id -i ~/.ssh/id_ed25519.pub tris@tris-k8slab-08
We then need to ensure that the account you are going to use for sudo is also added to the sudoers on the new host so that it is able to make the changes required when the Ansible playbook is run.
I need each server to allow this user to get sudo without a password, so on each server ensure the following:
sudo visudoAdd the user to the file (same as root):
tris ALL=(ALL:ALL) ALL NOPASSWD: ALLYou should now be able to SSH to a server as this user and gain sudo without re-entering the user’s password.
Update Inventory
Within the inventory.ini file found in the location below, and which we edited earlier, we need to add the information regarding the new node (07) we are now adding.
$ cd ~/kubespray/inventory/sample inventory/k8scluster1/inventory.iniSo for example:
# This inventory describe a HA typology with stacked etcd (== same nodes as control plane)
# and 3 worker nodes
# See https://docs.ansible.com/ansible/latest/inventory_guide/intro_inventory.html
# for tips on building your # inventory

# Configure 'ip' variable to bind kubernetes services on a different ip than the default iface
# We should set etcd_member_name for etcd cluster. The node that are not etcd members do not need to set the value,
# or can set the empty string value.
[all]
tris-k8slab-02 ansible_host=192.168.101.152 etcd_member_name=tris-k8slab-02 ansible_user=tris
tris-k8slab-03 ansible_host=192.168.101.153 etcd_member_name=tris-k8slab-03 ansible_user=tris
tris-k8slab-04 ansible_host=192.168.101.154 etcd_member_name=tris-k8slab-04 ansible_user=tris
tris-k8slab-05 ansible_host=192.168.101.155 ansible_user=tris
tris-k8slab-06 ansible_host=192.168.101.156 ansible_user=tris
tris-k8slab-07 ansible_host=192.168.101.158 ansible_user=tris
tris-k8slab-08 ansible_host=192.168.101.159 ansible_user=tris

[kube_control_plane]
tris-k8slab-02
tris-k8slab-03
tris-k8slab-04

[etcd]
tris-k8slab-02
tris-k8slab-03
tris-k8slab-04

[kube_node]
tris-k8slab-05
tris-k8slab-06
tris-k8slab-07
tris-k8slab-08

[calico_rr]

[etcd:children]
kube_control_plane
kube_node
calico_rr
Ensuring we add it as another “kube_node”, i.e. a worker.
Run Ansible Playbook
Run the playbook
cd ~/kubespray
source .venv/bin/activate

ansible-playbook -i inventory/k8scluster1/inventory.ini cluster.yml -K -b -v --private-key=~/.ssh/id_ed25519

kubectl label nodes tris-k8slab-07 kubernetes.io/role=worker
kubectl label nodes tris-k8slab-08 kubernetes.io/role=worker
Deploy a WebUI (Dashboard/Headlamp)
Dashboard used to be the go to, but it is now deprecated, so we’re going to use Headlamp instead.
We’re going to deploy Headlamp.
Get the YAML File from Headlamp
wget the YAML configuration
mkdir ~/kubernetes/headlamp
cd ~/kubernetes/headlamp
wget https://raw.githubusercontent.com/kubernetes-sigs/headlamp/main/kubernetes-headlamp.yaml
Create a Service Account Token
Before we go any further we require a Service Account with sufficient permissions to be created, we can create this via imperative commands as below, but I prefer declartively creating, so see below
Imperative
Create the Service Account, Cluster Role Binding and generate the token via imperative commands:
kubectl -n kube-system create serviceaccount headlamp-admin
kubectl create clusterrolebinding headlamp-admin --serviceaccount=kube-system:headlamp-admin --clusterrole=cluster-admin
kubectl create token headlamp-admin -n kube-system
Declarative
Create the Service Account, Cluster Role Binding and generate the token via a declarative statement in the form of a YAML file, which creates a Service Account called “headlamp-admin”, then creates a Cluster Role Binding to bind the Service Account to the Cluster Role “cluster-admin” to actually give it the trousers (privileges) to do what it needs to do.
headlamp-service-account.yaml
apiVersion: v1
kind: ServiceAccount
metadata:
  name: headlamp-admin
  namespace: kube-system
---
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRoleBinding
metadata:
  name: headlamp-admin
roleRef:
  apiGroup: rbac.authorization.k8s.io
  kind: ClusterRole
  name: cluster-admin
subjects:
- kind: ServiceAccount
  name: headlamp-admin
  namespace: kube-system
Now we apply this with:
kubectl apply -f headlamp-service-account.yamlNote however, here is where the generation of the token is still an imperative statement, we just need this value to plug into the web interface in a later step, so keep a copy!
kubectl create token headlamp-admin -n kube-systemNow we have this token and the Service Account created (and bound to a cluster role), we are ready for deployment!
https://headlamp.dev/docs/latest/installation/#create-a-service-account-token.
Deploy Headlamp
Deploy with:
kubectl apply -f kubernetes-headlamp.yamlAssuming all is well, you should then see the application is now available on a LoadBalancer IP address.

We can see it there in the middle on 192.168.101.162, so let’s try to access it from a web browser on our client machine.
Configure Headlamp Authentication
We connect via a web browser, and then enter our token, then click “Authenticate”.
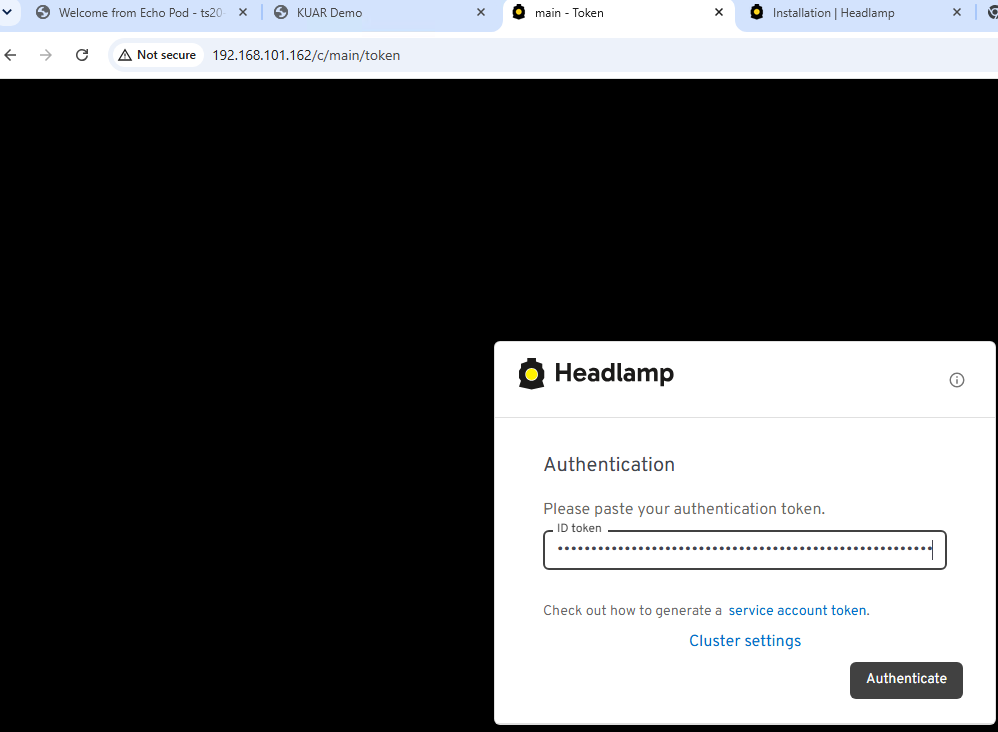
All being well, we should now see a dashboard like the following, which shows the deployment and configuration has been successful.
Conclusion
We’ve now completed the deployment of Kubernetes with Kubespray, there’s still much more to explore in the coming articles.
Additional Information/Further Reading
- https://fschoenberger.dev/homelab/03-deploy-k8s-kubespray
- https://medium.com/@leonardo.bueno/setting-up-a-kubernetes-cluster-with-kubespray-1bf4ce8ccd73
- https://fschoenberger.dev/homelab/03-deploy-k8s-kubespray
- https://kubernetes.io/docs/tasks/access-application-cluster/web-ui-dashboard/
- https://schoolofdevops.github.io/ultimate-kubernetes-bootcamp/cluster_setup_kubespray/